Apache Druid
Overview
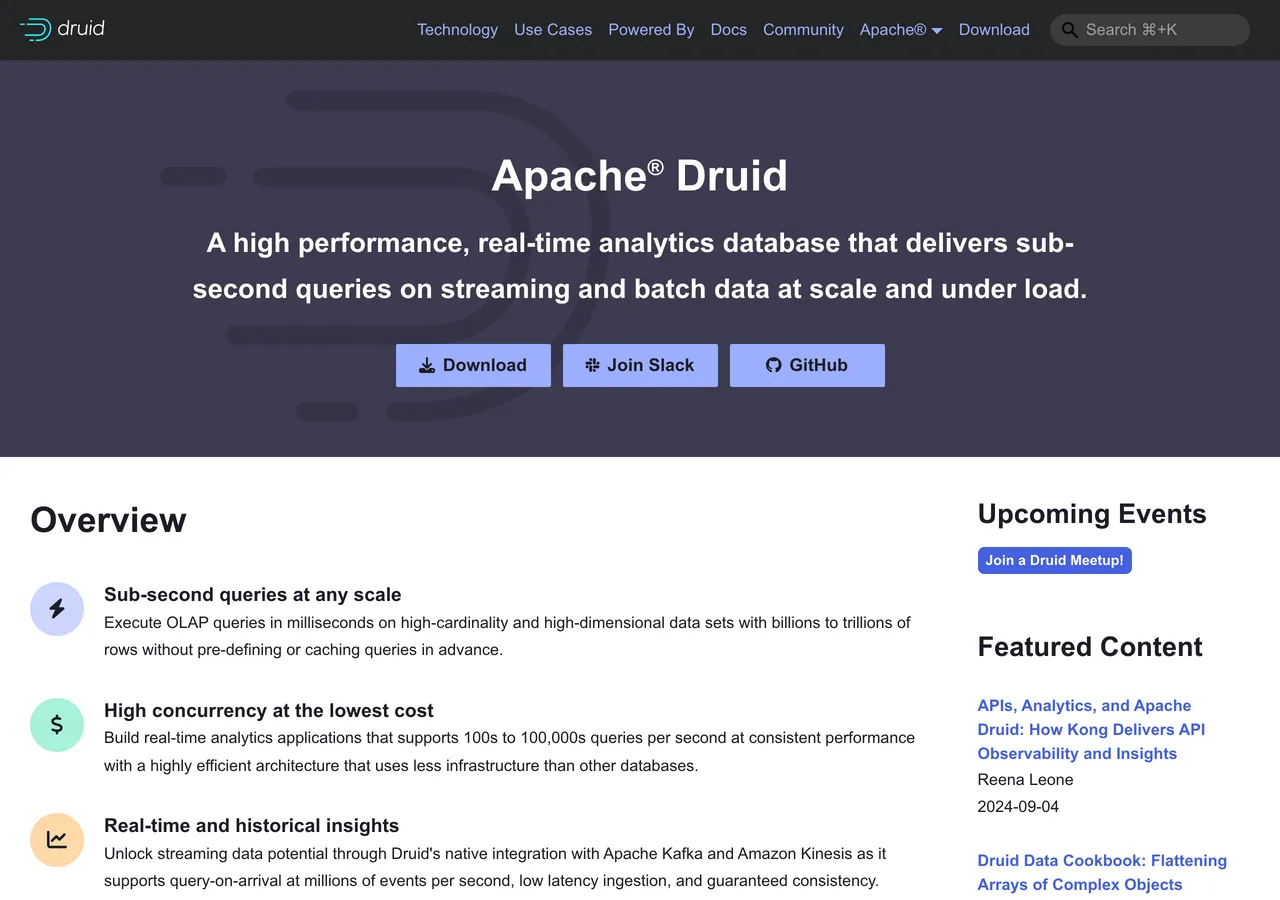
Apache Druid is a high-performance, real-time analytics database. It runs sub-second queries on streaming and batch data, even with billions or trillions of rows and many users querying at once, and is often used to power analytics UIs and dashboards.
What it does well
Druid ingests streams natively from Apache Kafka and Amazon Kinesis, so data can be queried as it arrives, alongside historical data. It handles hundreds to hundreds of thousands of queries per second with consistent performance. Data is preloaded into memory or local storage to avoid network delays, and tiering lets you balance cost and speed for different workloads.
Why it’s in the collection
Druid is built for the cases where a regular data warehouse is too slow: live dashboards and user-facing analytics. It's an Apache project, Apache-licensed.
On GitHub
- Stars
- 0
- Forks
- 0
- Commits
- 0
- Repository
- apache/druid
Languages
- Java 83.9%
- ReScript 8.5%
- TypeScript 4.4%
- Other 3.2%
Compared with
- SSnowflakeCommercial cloud data warehouse.
 Google BigQueryGoogle's serverless data warehouse.
 Amazon RedshiftAWS's data warehouse.
 ClickHouseNo. 012Open-source column-oriented database for analytics.
See every open-source alternative to Snowflake and BigQuery in the collection.