- About
- Open-source engine for fast, efficient LLM serving.
- Catalogue
- No. 201
- Category
- AI
- GitHub stars
- ★ 0
Overview
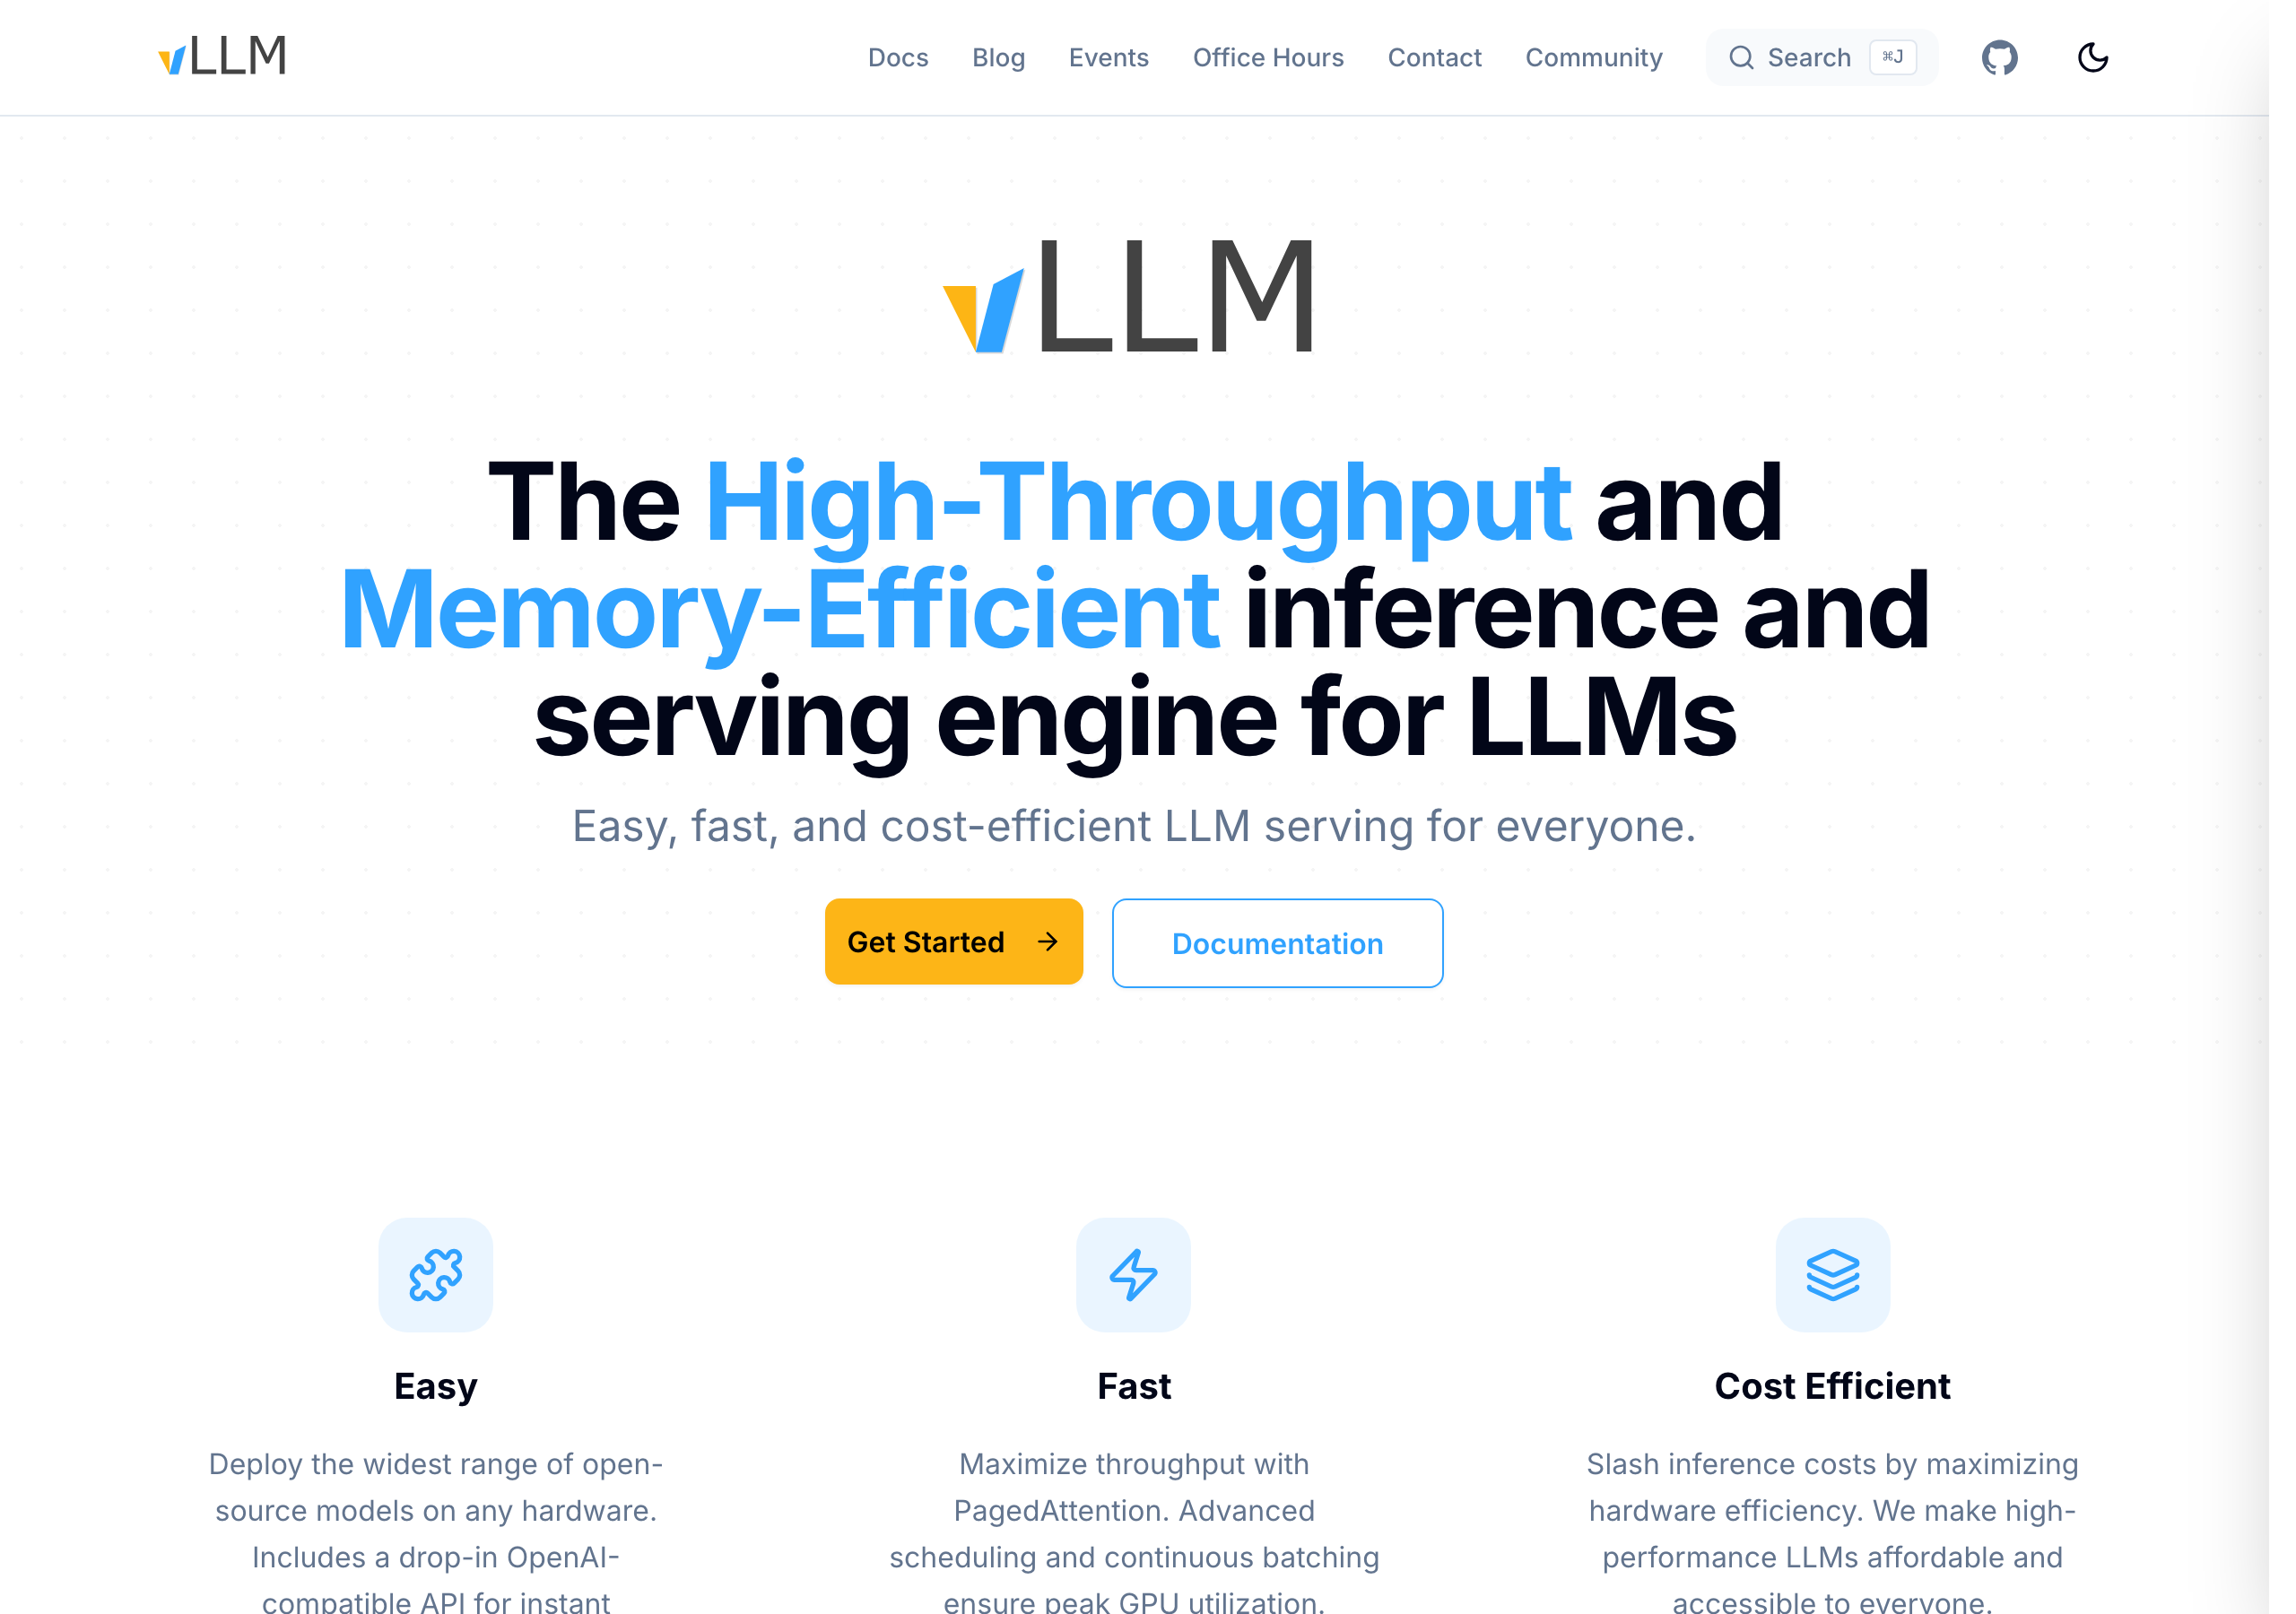
vLLM is a fast, easy-to-use library for serving large language models. It was originally developed in the Sky Computing Lab at UC Berkeley and is now one of the most active open-source AI projects, maintained by a broad community.
What it does well
vLLM delivers high serving throughput through PagedAttention memory management, continuous batching, chunked prefill and prefix caching. It supports many quantization formats (FP8, INT4, GPTQ, AWQ, GGUF and more), optimised attention kernels, speculative decoding, and disaggregated prefill and decode.
Why it’s in the collection
vLLM is the standard engine teams use to serve open models in production at high throughput. It is Apache-licensed.
On GitHub
- Stars
- 0
- Forks
- 0
- Commits
- 0
- Repository
- vllm-project/vllm
Languages
- Python 85.4%
- Rust 6.4%
- Cuda 3.9%
- C++ 3%
- Other 1.3%
 OpenAI API
 Together AI
 LocalAI