Crawl4AI
- About
- Open-source web crawler that turns websites into LLM-ready Markdown. Open-source alternative to Apify.
- Catalogue
- No. 222
- Category
- Data & Content
- GitHub stars
- ★ 0
Overview
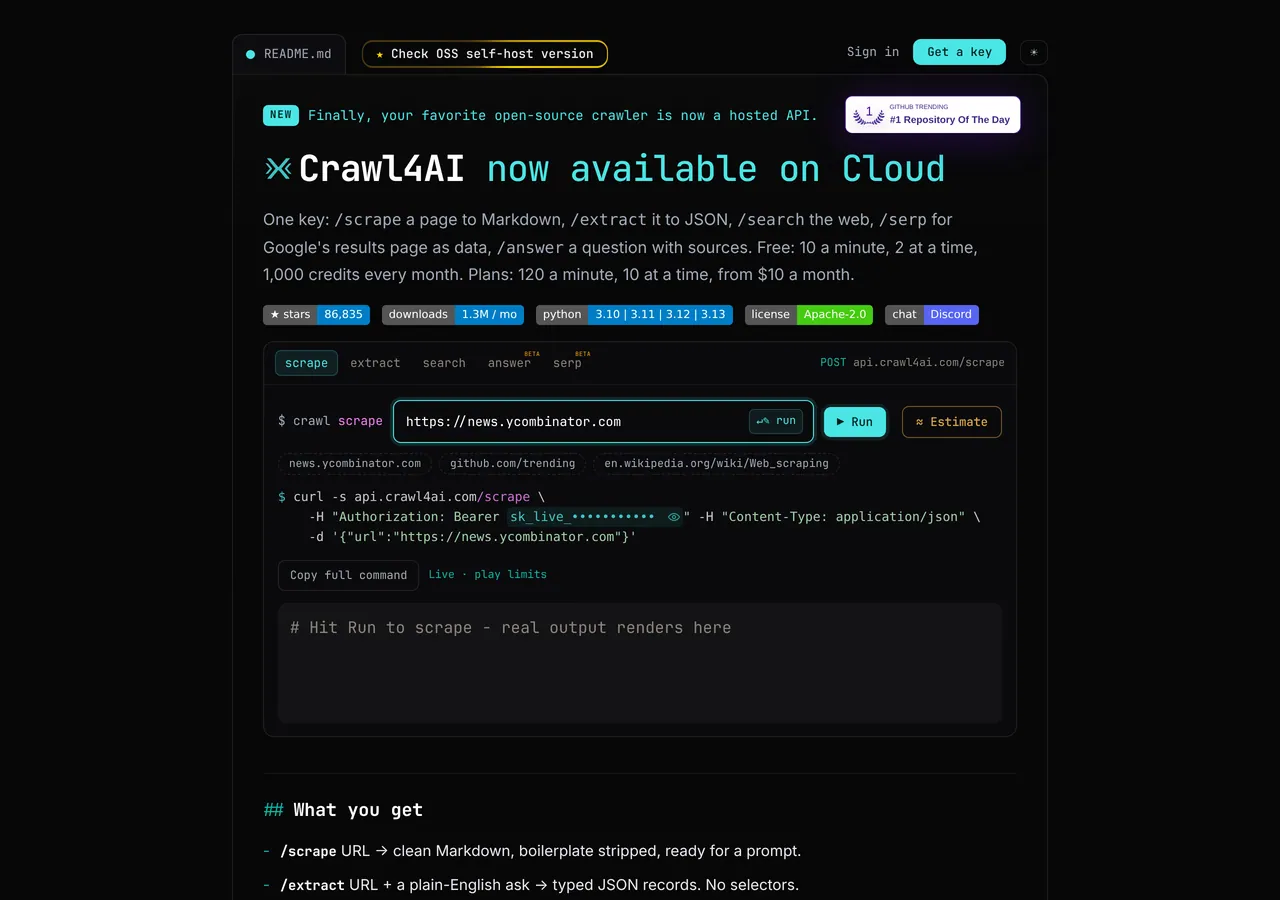
Crawl4AI is an open-source web crawler and scraper for LLMs and AI agents. It turns any website into clean Markdown for RAG, agents and data pipelines. You can run it as a Python library, as your own server in Docker, or from the command line; a hosted cloud version is also available.
What it does well
Crawl4AI produces Markdown that keeps headings, tables and code, filters out menus and boilerplate, and turns links into numbered citations. It extracts structured JSON with CSS or XPath schemas, or with any LLM, and can generate a reusable schema from a description. It drives a real browser with persistent profiles, sessions, proxies and hooks, and an async browser pool with caching keeps large crawls fast.
Why it’s in the collection
Crawl4AI does the job that most AI projects need before anything else, getting clean text out of the web, without an account or API key. You run it yourself for free, and only pay if you choose the hosted version.
On GitHub
- Stars
- 0
- Forks
- 0
- Commits
- 0
- Repository
- unclecode/crawl4ai
Languages
- Python 83.4%
- HTML 15.8%
- JavaScript 0.7%
- Other 0.1%
Compared with
 ApifyHosted web scraping and automation platform, priced by usage.
 BrowserbaseHosted headless browsers for AI agents and scraping.
 FireCrawlNo. 040Web scraping API that turns sites into LLM-ready data.
See every open-source alternative to Apify in the collection.